Data scientists, ML engineers, and research teams running CPU-based machine learning workloads

Dedicated Server for Machine Learning UK

Train models, serve inference, and process datasets on UK dedicated hardware. Dual Xeon, up to 64GB RAM, NVMe storage, and full root access. From £49/mo.

Dedicated server for machine learning UK

The Problem

Common Challenges for Data scientists, ML engineers, and research teams running CPU-based machine learning workloads

These are the issues that consistently come up when Data scientists, ML engineers, and research teams running CPU-based machine learning workloads try to scale on the wrong infrastructure.

Challenge 1

Cloud GPU instances bill per-hour - a training job that overruns or a serving endpoint that stays up 24/7 generates unpredictable costs

Challenge 2

Shared VPS memory limits prevent loading large datasets into memory - critical for pandas, Spark, and in-memory ML training workflows

Challenge 3

Cloud ML platforms (SageMaker, Vertex AI) add vendor lock-in and platform-specific tooling that doesn't transfer between providers

How We Help

How Glitch Servers Solves This

Machine learning workloads range from training small models on CPU to serving inference at scale. For CPU-based ML (scikit-learn, XGBoost, smaller PyTorch models), cloud GPU instances are overkill - a dedicated Xeon server with high memory and NVMe storage handles training and inference at a fraction of the cost. For teams that need consistent, predictable compute for data pipelines, model training, and API-based model serving, dedicated hardware provides fixed monthly cost without per-hour billing surprises.

External resources: LINX (London Internet Exchange) and RIPE NCC (European IP registry).


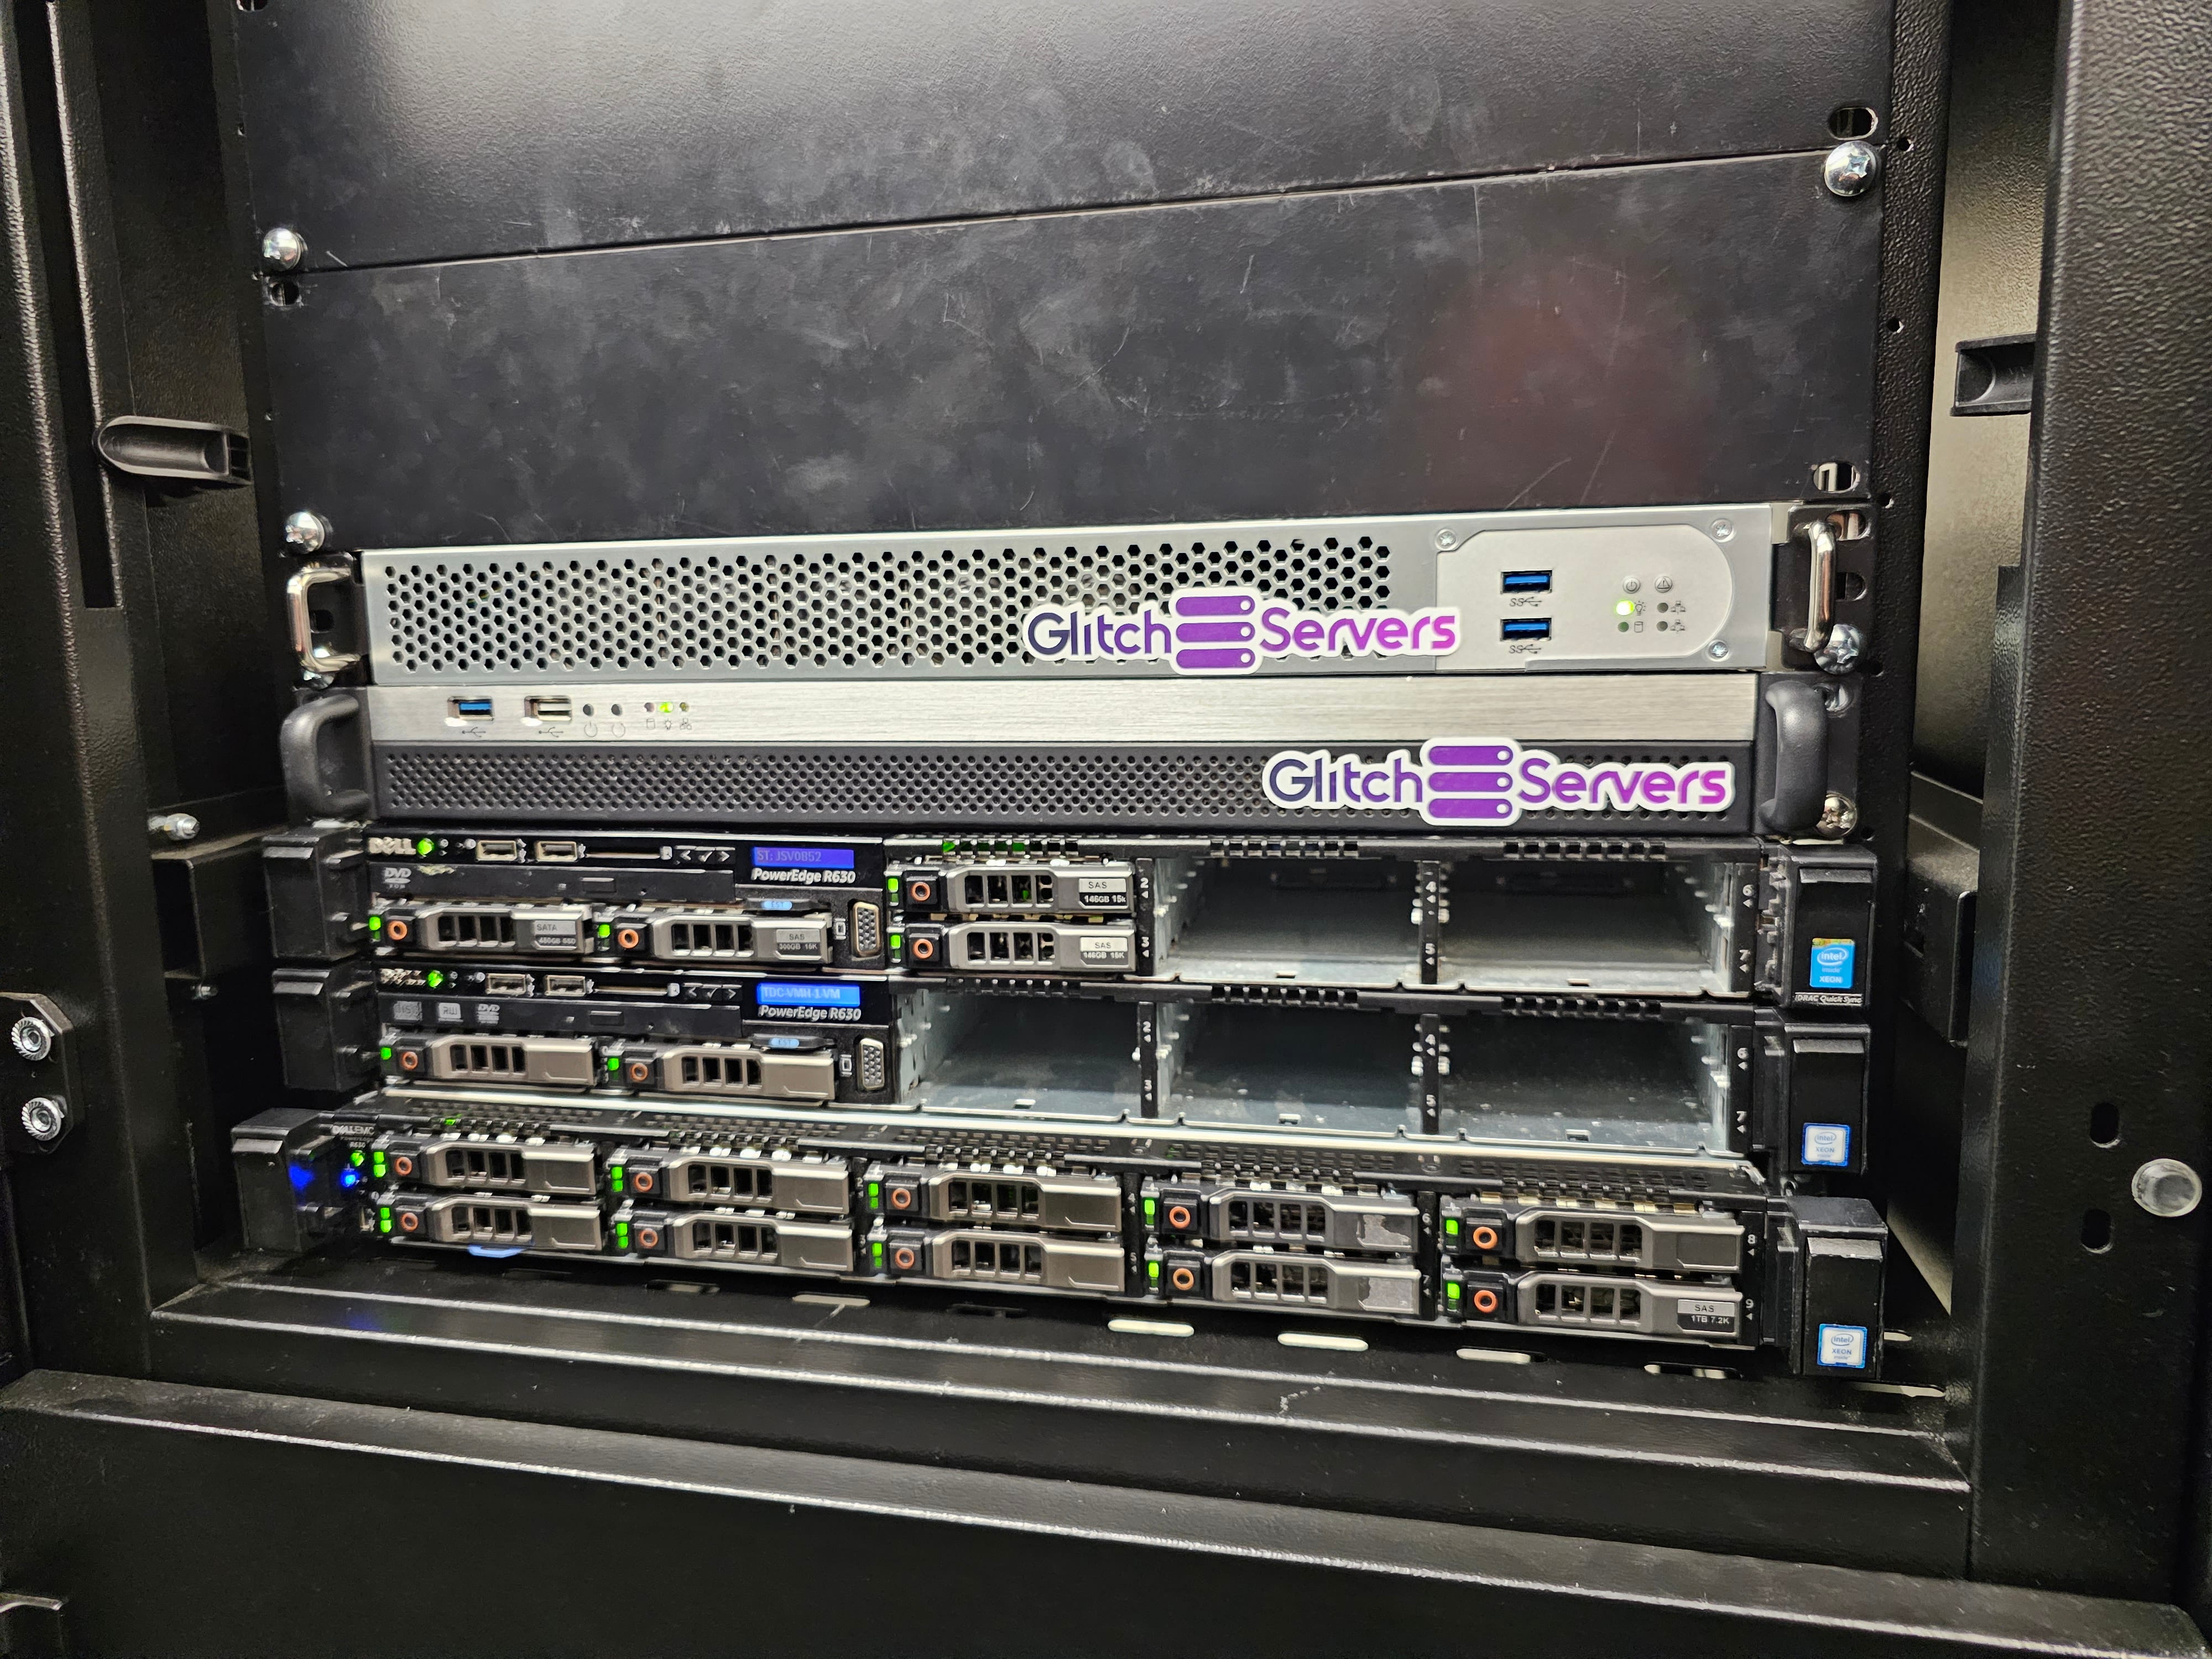
A Glitch Servers dedicated server provides fixed-cost ML infrastructure. Dual Xeon E5 with 64GB RAM loads large datasets entirely into memory for fast training iterations. NVMe storage handles data pipeline I/O at 3,000+ MB/s. Install PyTorch, TensorFlow, scikit-learn, Jupyter, or any ML framework with full root access. No per-hour billing - train as many models as you want for a flat monthly fee. For GPU workloads, ask about our GPU dedicated server options.
What You Get

Built for Data scientists, ML engineers, and research teams running CPU-based machine learning workloads

The features that matter most for your workload, included as standard.

Up to 64GB RAM

Load entire datasets into memory for fast training. Dual Xeon with 64GB DDR4 handles large pandas DataFrames, in-memory feature engineering, and model training without swapping to disk.

🛡

NVMe Data Pipeline I/O

Read training data from NVMe at 3,000+ MB/s. Data loading is never the bottleneck - your training loop runs at CPU speed, not disk speed.

🔧

Any ML Framework

Full root access to install PyTorch, TensorFlow, scikit-learn, Jupyter, MLflow, or any tool. Configure CUDA (if GPU), conda environments, and Docker containers exactly as your workflow requires.

💰

Fixed Monthly Cost

No per-hour compute billing. Train models all day, serve inference 24/7, and run data pipelines continuously for a flat £49-79/mo depending on spec.

Trust Signals

Infrastructure You Can Rely On

99.9%
Uptime SLA
100G
Backbone Capacity
AS212868
Own Network ASN
24/7
UK-Based Support
UK machine learning dedicated server

FAQ

Frequently Asked Questions

Small to medium neural networks train on CPU, but slowly compared to GPU. For large deep learning models, GPU hardware is recommended. For classical ML (XGBoost, random forests, SVMs, regression), CPU is the correct and most cost-effective choice.
Yes. We offer GPU dedicated server options for deep learning training and inference workloads. Contact us for GPU availability and pricing.
Yes. Install JupyterHub or JupyterLab with full root access. Access notebooks via browser over SSH tunnel or configure HTTPS access. Multi-user JupyterHub supports entire teams.

ML Infrastructure from £49/mo

Up to 64GB RAM · NVMe I/O · Any framework · Fixed cost · UK datacentre

View Plans →