AI & GPU Colocation UK
AI Inference Hosting UK
NVIDIA GPU inference servers in UK data centres - deploy vLLM, Triton, and custom inference APIs with low latency
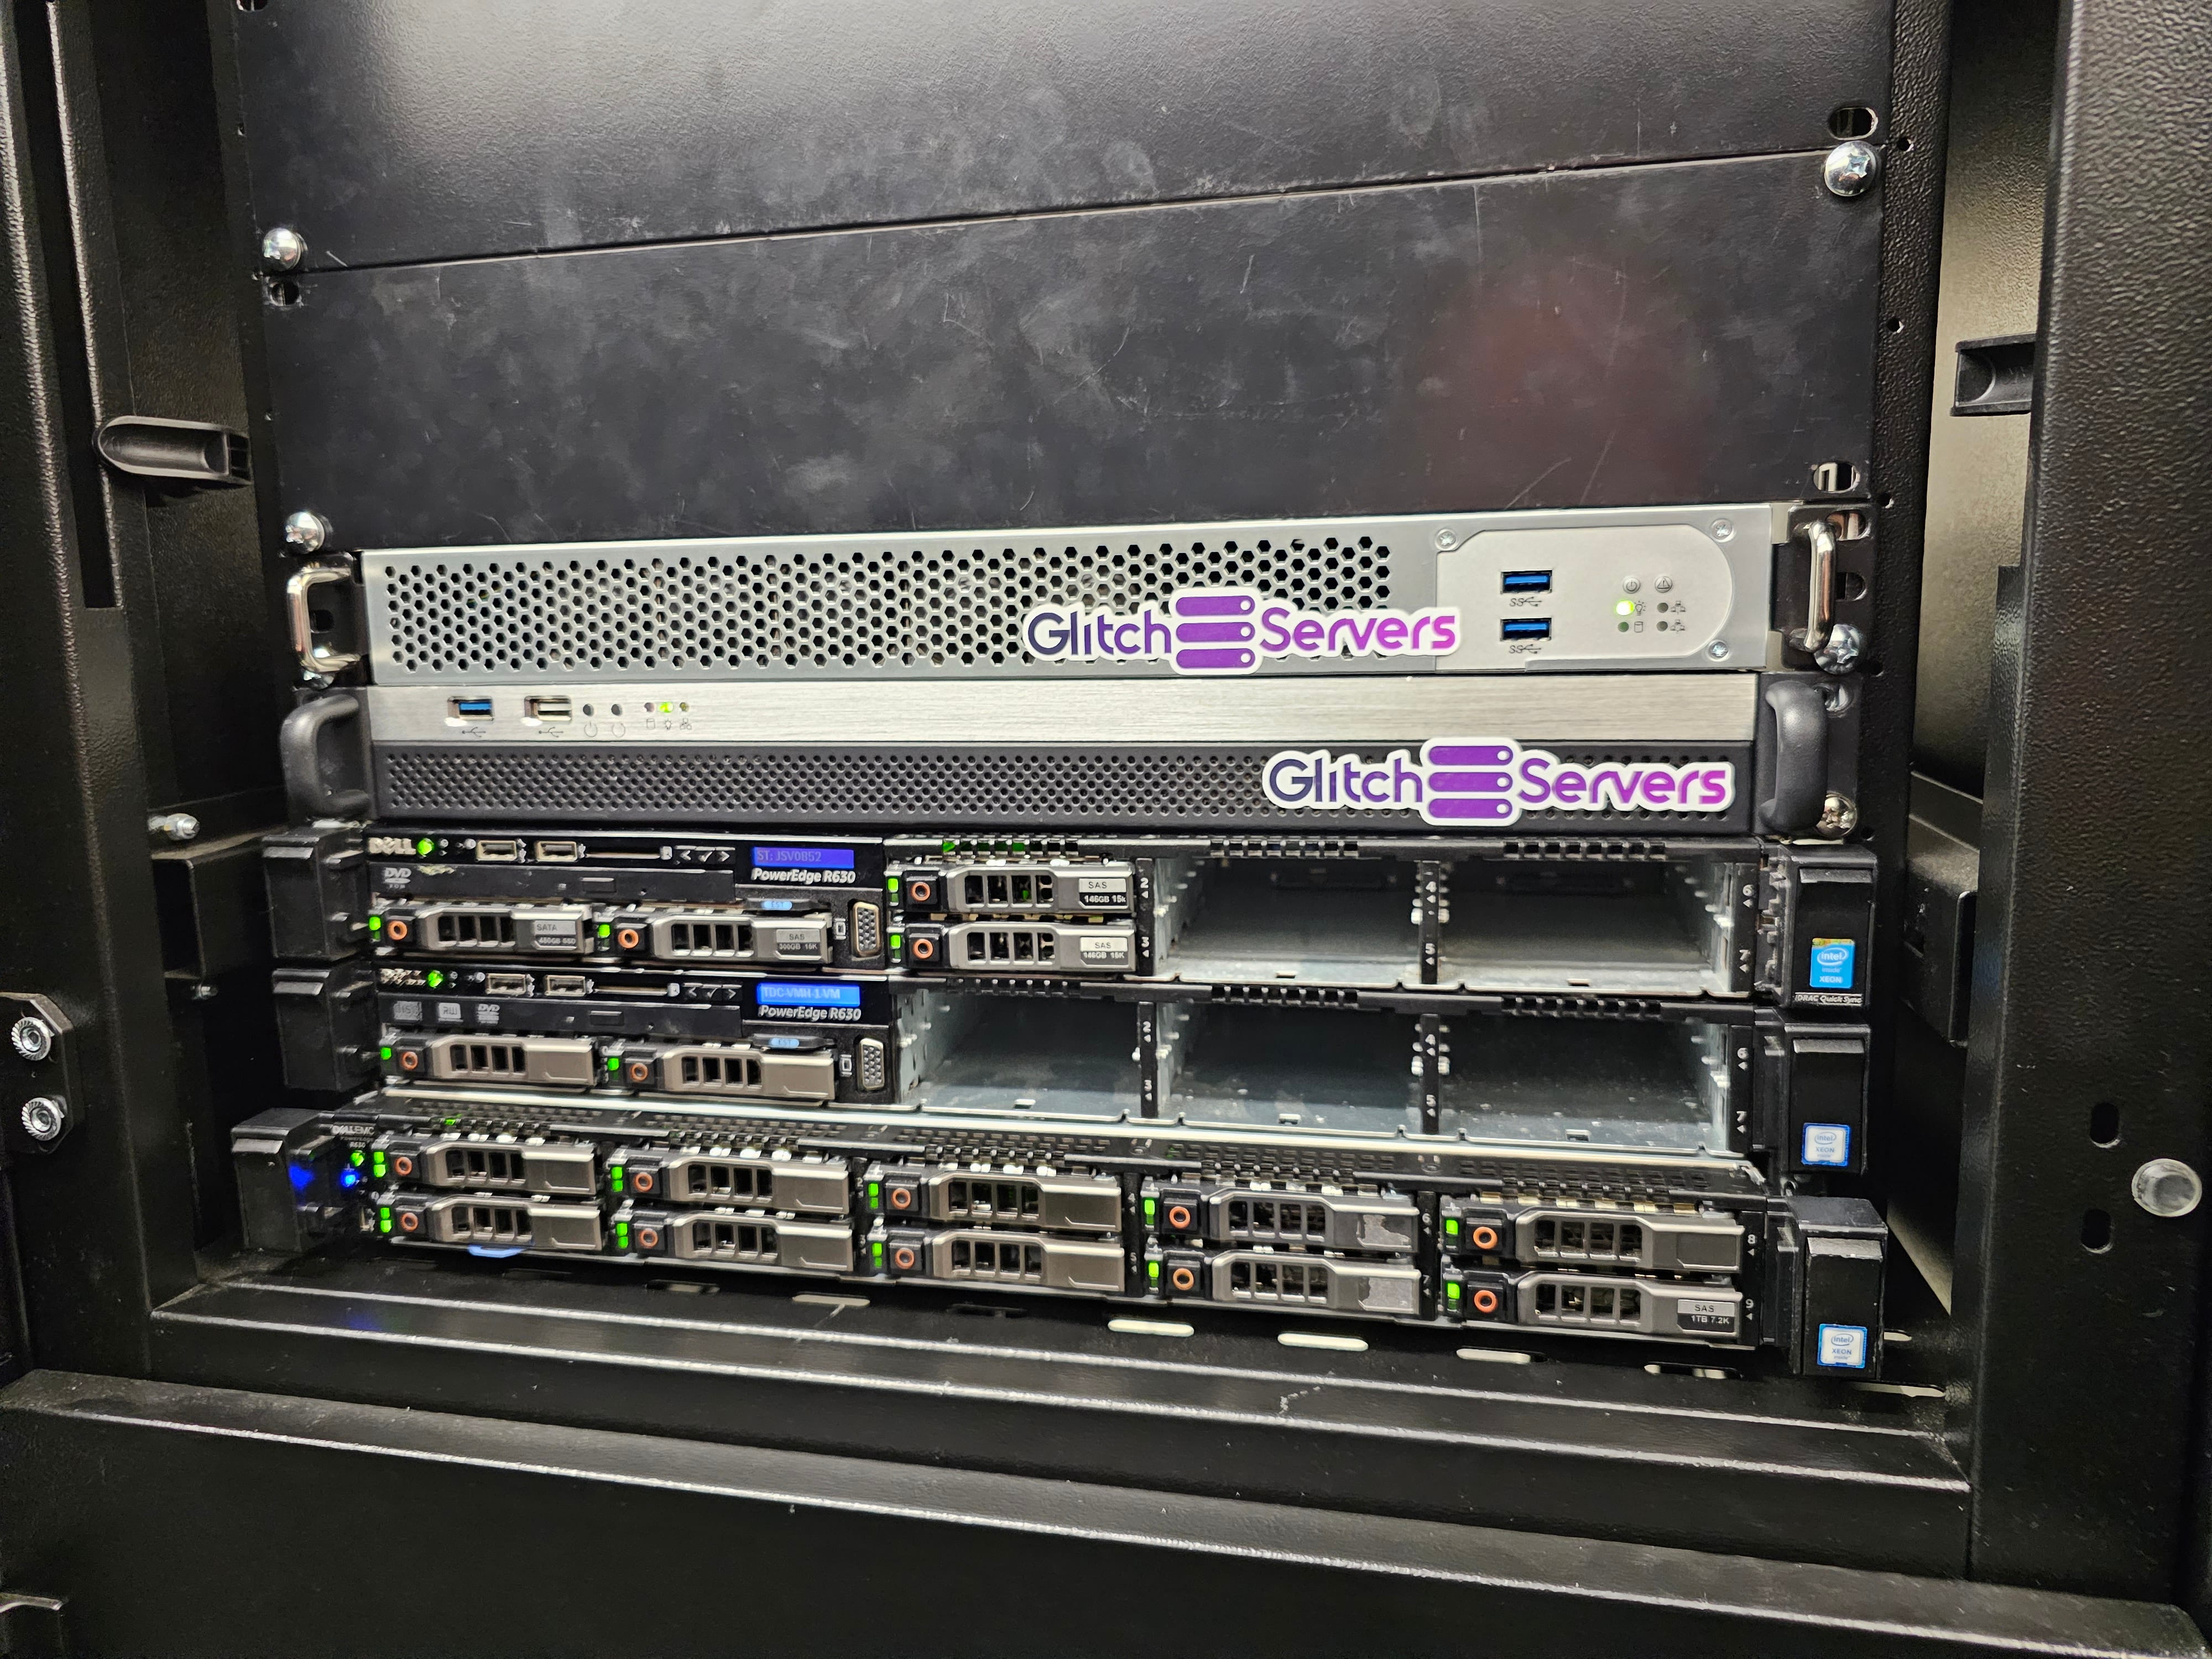
NVIDIA GPU inference servers in UK data centres - deploy vLLM, Triton, and custom inference APIs with low latency
About This Service
AI Inference Hosting UK from Glitch Servers provides carrier-neutral rack space with direct LINX and LONAP connectivity - backed by AMD Ryzen hardware, NVMe Gen4 storage, and UK-native routing through AS212868. Training large language models requires sustained GPU access over days or weeks, but inference - serving predictions to end users - is a different workload entirely. Inference demands low-latency response times, high throughput for concurrent requests, and efficient GPU memory management for model loading. Our UK AI inference hosting provides NVIDIA L40S (48GB GDDR6) and A100 (80GB HBM2e) GPU servers configured for inference serving, running vLLM, NVIDIA Triton Inference Server, or custom FastAPI/uvicorn stacks. UK data centres reduce latency for European and UK API consumers, and data residency requirements are simplified for regulated applications.
Colocation at Glitch Servers is carrier-neutral, meaning you are not locked to a single upstream provider. The facility connects to LINX and LONAP through AS212868, giving colocated customers access to over 800 networks reachable directly via the UK's primary internet exchanges without paying Tier-1 transit rates for every byte. Power infrastructure is N+1 redundant with UPS and generator backup.
BGP multi-homing through NTT and GTT Tier-1 upstream carriers provides path diversity and automatic failover if a single transit provider experiences degradation. Remote hands are available 24/7 for customers who need physical access assistance, hardware reboots, or cabling work without travelling to the facility.
UK data sovereignty is preserved by design - traffic from colocated servers traverses UK and Irish exchange points before reaching international networks, supporting GDPR and UK GDPR compliance requirements for data residency. Full rack options and pricing are detailed on the UK colocation page.
Technical Capabilities
High-density power, low-latency networking, and carrier-neutral connectivity for demanding GPU clusters.
NVIDIA L40S 48GB GDDR6 - efficient inference for 7B–70B parameter models
A100 80GB HBM2e - maximum VRAM for large model inference
NVMe RAID SSD - fast model loading, seconds to first inference
UK data centres - API request data stays in UK jurisdiction for GDPR compliance
Ideal Customers
We work with a range of organisations running compute-intensive AI workloads on owned hardware.
AI API Developers
SaaS Builders
Research Teams
Infrastructure
Our UK AI inference infrastructure runs NVIDIA L40S and A100 GPU servers on Intel Xeon platforms in UK-based data centres with A 10Gbps burst port is available for distributed-training traffic. NVMe SSD RAID arrays provide fast model weight loading, and our CUDA 12.x environment with Ubuntu 22.04 is ready for vLLM, Triton, and custom inference stacks. UK data residency ensures API request data stays within UK jurisdiction for GDPR-compliant AI applications.
FAQ
Enquire about UK AI inference hosting from £199/mo
L40S and A100 GPU servers. vLLM ready. UK data residency.
Enquire Now →